Black Friday, 20:15. The checkout page of an online store displays, below the cart, a small carousel: “Customers who bought this also bought…”. The recommendations come from a separate microservice, which tonight started responding in 8 seconds instead of 80 milliseconds.
The team did everything by the book: 3-second timeout per attempt, 2 retries with jitter. The result: each checkout now waits up to 9 seconds for a carousel that no one looks at. Connections to the recommendation service accumulate, the HTTP connection pool grows, memory usage rises. At 20:40, even payments stop going through, although the payment service is perfectly healthy.
The retry did exactly what it was asked: it insisted. The problem is that sometimes the smartest thing you can do with a sick dependency is to not call it at all for a while, and when you do call it, not allow it to consume the resources needed by the rest of the functionalities. That’s what the two patterns in this article do: circuit breaker and bulkhead.
Circuit breaker: the fuse in the electrical panel
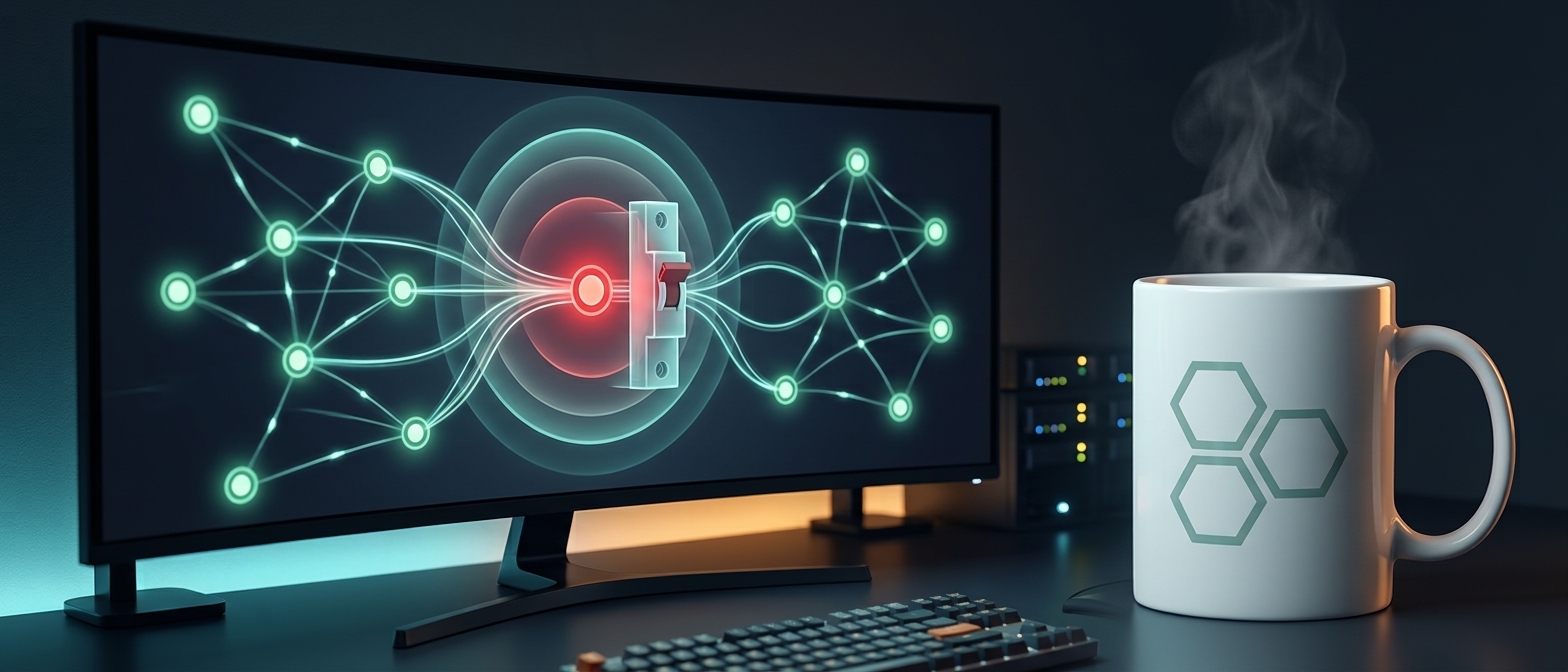
The analogy in the name is exact. The automatic fuse in the electrical panel does not fix the short circuit. It only cuts the power before the wires catch fire. Once triggered, no current passes through that circuit, and the rest of the house functions normally.
In software, the circuit breaker sits between your code and a dependency, monitors the result of calls, and when the failure rate exceeds a threshold, it “trips”. From that moment, all calls to the dependency fail immediately, without going over the network. Two things happen simultaneously:
- Your application protects itself. An instant failure costs microseconds. A timeout costs seconds, connections, and memory. Instead of waiting 9 seconds for an error you already know, you get it immediately and move on to plan B.
- The dependency gets a break. An overloaded service needs pressure relief to recover. Retries send it more traffic exactly when it cannot process it. The circuit breaker cuts off the traffic completely.
Retry and circuit breaker are not alternatives but complement each other. Retry handles short and isolated failures: a reset connection, a 503 for one second. Circuit breaker handles persistent and widespread failures: a dependency that has been down for several minutes.
The three states
- Closed — the normal state. Calls pass through, and the breaker counts successes and failures within a time window. When the failure rate exceeds the threshold, it moves to Open.
- Open — the circuit is open. No calls go to the dependency. All fail immediately with
BrokenCircuitException. This state lasts for a configured period (break duration). - Half-Open — the pause period has expired. The breaker allows one test call through, while others continue to be rejected. If the test succeeds, the circuit closes and traffic returns to normal. If it fails, the circuit reopens for another period.
The Half-Open state is what makes the pattern elegant. The breaker doesn’t need a separate mechanism to check if the dependency has recovered: it uses real traffic, but in minimal doses.
Circuit breaker in Polly v8
In Polly v8 there is a single type of circuit breaker, based on the failure rate within a time window. The variant from older versions, based on a fixed number of consecutive failures, has disappeared, and for good reason: three consecutive failures mean something different at 5 requests per minute than at 5,000 per second.
builder.Services.AddResiliencePipeline<string, HttpResponseMessage>("recomandari", (pipeline, context) =>
{
    var logger = context.ServiceProvider
        .GetRequiredService<ILoggerFactory>()
        .CreateLogger("Resilience.Recomandari");

    pipeline.AddCircuitBreaker(new CircuitBreakerStrategyOptions<HttpResponseMessage>
    {
        FailureRatio = 0.5,
        MinimumThroughput = 10,
        SamplingDuration = TimeSpan.FromSeconds(30),
        BreakDuration = TimeSpan.FromSeconds(15),
        ShouldHandle = new PredicateBuilder<HttpResponseMessage>()
            .Handle<HttpRequestException>()
            .Handle<TimeoutRejectedException>()
            .HandleResult(r => (int)r.StatusCode >= 500),
        OnOpened = args =>
        {
            logger.LogError("Circuit opened for {Duration}s", args.BreakDuration.TotalSeconds);
            return default;
        },
        OnClosed = _ =>
        {
            logger.LogInformation("Circuit closed, recommendation service has recovered");
            return default;
        }
    });
});
The above configuration reads as: if, in the last 30 seconds, there have been at least 10 calls and at least half have failed, open the circuit for 15 seconds.
How to choose the values
FailureRatio— failure threshold, between 0 and 1. The default value, 0.1, is aggressive: the circuit trips at 10% errors. It’s suitable for critical and stable dependencies, where 10% errors already mean a real problem. For known unstable dependencies, a threshold of 0.3–0.5 avoids unnecessary openings.MinimumThroughput— minimum number of calls in the window before the rate counts. Without it, 1 failure out of 2 calls would be 50% and open the circuit. Beware of the flip side: if the dependency has low traffic, e.g., 5 calls per minute, and the threshold is 100 (the default), the circuit will never open.SamplingDuration— observation window. It must be at least twice as long as the timeout per attempt, otherwise a window won’t see enough completed calls. The standard handler validates this rule at startup.BreakDuration— how long the circuit remains open. Too short and you hit a service that hasn’t recovered again. Too long and you stay degraded longer than necessary. 15–30 seconds is a reasonable starting point for most APIs.
Adaptive break duration
If the circuit reopens multiple times in a row, the dependency clearly has a serious problem. Testing it every 15 seconds doesn’t help anyone. BreakDurationGenerator allows increasing the pause after each failed test, following the same principle as exponential backoff from the article about retry:
BreakDurationGenerator = args =>
{
    // 15s, 30s, 60s, 120s... maximum 5 minutes
    double seconds = 15 * Math.Pow(2, args.HalfOpenAttempts);
    return ValueTask.FromResult(TimeSpan.FromSeconds(Math.Min(seconds, 300)));
}
Order in the pipeline: retry, then circuit breaker
In the first article we saw that the order of strategies matters. For retry and circuit breaker, the correct order is almost always this:
pipeline
    .AddTimeout(TimeSpan.FromSeconds(10))   // total timeout
    .AddRetry(retryOptions)                 // retry
    .AddCircuitBreaker(breakerOptions)      // sees EACH attempt
    .AddTimeout(TimeSpan.FromSeconds(2));   // timeout per attempt
The circuit breaker sits inside the retry, so it sees each individual attempt, including the timeouts per attempt. When the circuit opens, the next retry receives instantly BrokenCircuitException, instead of going over the network.
Here arises an important decision: should retry retry BrokenCircuitException? Generally, no. An open circuit is an explicit signal that the dependency is down for at least a few seconds. Retrying after 500 ms means getting the same exception, just later. Leave BrokenCircuitException out of the retry’s ShouldHandle predicate and handle it at the caller.
What to do when the circuit is open
The circuit breaker doesn’t solve anything by itself. It only turns a long wait into a fast error. What you do with that error is your business decision:
public async Task<IReadOnlyList<Product>> GetRecommendationsAsync(int productId, CancellationToken ct)
{
    try
    {
        return await _pipeline.ExecuteAsync(
            async token => await _client.GetRecommendationsAsync(productId, token), ct);
    }
    catch (BrokenCircuitException)
    {
        // Recommendations are optional: checkout proceeds without them
        return [];
    }
}
For recommendations, the answer is simple: empty carousel, functional checkout. For a critical dependency, it might be a 503 response with a Retry-After header, a cached value, or queuing the operation. All these options are the subject of article 5, about graceful degradation. What matters now is that the decision is made in milliseconds, not after 9 seconds.
One breaker per dependency, not a global one
The granularity of the circuit breaker is a design decision as important as the thresholds. One breaker for all external calls would mean that a problem in the recommendation service blocks payments too. The rule: one breaker per dependency, and when a dependency has multiple hosts, per host.
The standard handler in Microsoft.Extensions.Http.Resilience creates one pipeline per HTTP client. If the same client calls multiple hosts, for example a regional API on multiple domains, you can separate pipelines by authority:
builder.Services
    .AddHttpClient<ISupplierClient, SupplierClient>()
    .AddStandardResilienceHandler()
    .SelectPipelineByAuthority();
Thus, api-eu.supplier.example and api-us.supplier.example have independent circuits. A problem in one region does not block the other.
It’s also worth noting that the circuit breaker state is local to each instance. With 10 pods, you have 10 breakers deciding independently. Most of the time, that’s exactly what you want: each instance observes its own traffic. A distributed circuit breaker synchronized via Redis adds a new dependency right into the mechanism that should protect you from dependencies.
Manual control: maintenance windows
Sometimes you know in advance that a dependency will be down: the provider announced maintenance between 02:00 and 04:00. It doesn’t make sense to wait for the breaker to observe it by itself. Polly v8 allows manual opening of the circuit:
builder.Services.AddSingleton<CircuitBreakerManualControl>();

// in pipeline configuration:
ManualControl = context.ServiceProvider.GetRequiredService<CircuitBreakerManualControl>(),

// in an admin endpoint or scheduled job:
await manualControl.IsolateAsync(ct);   // circuit forced open
await manualControl.CloseAsync(ct);     // return to normal
As long as the circuit is manually isolated, calls receive IsolatedCircuitException, a subclass of BrokenCircuitException. The above handling code works without any modification.
Similarly, CircuitBreakerStateProvider tells you at any moment the current state (Closed, Open, HalfOpen, Isolated). It’s tempting to hook it directly to the Kubernetes readiness probe. Don’t do that without reading article 4: if all pods declare readiness failure because an external dependency is down, Kubernetes removes them all from the load balancer, turning a degraded functionality into a completely down application.
Bulkhead: watertight compartments
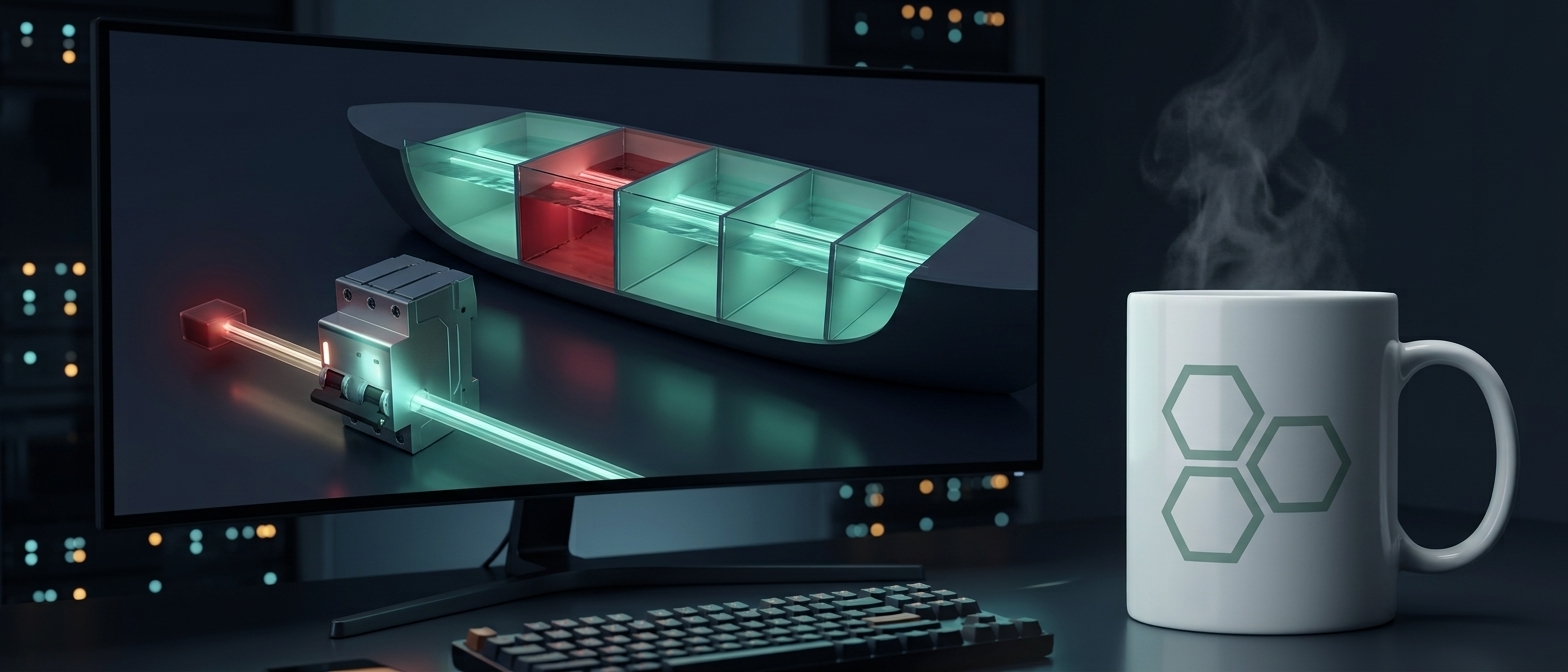
The name comes from ship construction. The hold of a ship is divided into watertight compartments. If one compartment takes on water, only that compartment floods, and the ship stays afloat. The Titanic sank, among other reasons, because the watertight walls did not extend all the way up, and water passed from one compartment to another.
In applications, “water” is resource consumption. Each ongoing call to a dependency occupies an HTTP connection, memory for request and response, maybe a connection from the SQL pool. If a single slow dependency can consume all these resources, it sinks the entire application. That’s exactly what happened in the story at the beginning.
The bulkhead puts a limit on the number of simultaneous calls to a dependency. If the limit is reached, new calls are rejected immediately or wait in a short queue. The recommendation service can have a maximum of 20 concurrent calls, and the 21st is rejected instantly. Payments have their own compartment, untouched.
Bulkhead in Polly v8: concurrency limiter
In Polly v8, bulkhead is implemented with a concurrency limiter, built on top of System.Threading.RateLimiting:
dotnet add package Polly.RateLimitingbuilder.Services.AddResiliencePipeline<string, HttpResponseMessage>("recomandari", pipeline =>
{
pipeline
.AddConcurrencyLimiter(permitLimit: 20, queueLimit: 10)
.AddTimeout(TimeSpan.FromSeconds(10))
.AddRetry(retryOptions)
.AddCircuitBreaker(breakerOptions)
.AddTimeout(TimeSpan.FromSeconds(2));
});Maximum 20 simultaneous calls, plus maximum 10 waiting. The 31st call receives RateLimiterRejectedException instantly. The limiter sits outside the pipeline, because you want to reject the request before it consumes any resource, including time spent in retries.
The standard handler already includes such a limiter, but with generous values: 1,000 simultaneous calls, no queue. It’s a safety net, not a tuned bulkhead. For important dependencies, adjust it:
.AddStandardResilienceHandler(options =>
{
    options.RateLimiter.DefaultRateLimiterOptions.PermitLimit = 20;
    options.RateLimiter.DefaultRateLimiterOptions.QueueLimit = 10;
});
How to choose the limit
Little’s law, from the first article, gives you a starting point. If the dependency receives 100 requests per second and responds normally in 100 ms, you have on average 10 concurrent calls. A limit 2–3 times above the normal average, i.e., 20–30, allows for traffic spikes but stops accumulation when latency explodes. At 8 seconds per response, the same 100 requests per second would produce 800 concurrent calls. With bulkhead, it stays at 20.
Bulkheads that already exist
It’s worth knowing that your application already has some compartments, even if you haven’t explicitly configured them, and some are shared, which makes them dangerous:
- The SQL Server connection pool has by default a maximum of 100 connections (
Max Pool Size). It’s a natural bulkhead for the database, but a common one for all queries. A slow report that holds 100 connections blocks login too. SocketsHttpHandler.MaxConnectionsPerServeris unlimited by default. Without a bulkhead, the number of connections to a slow dependency grows without limit.- The thread pool is shared by the entire application. Correct async code doesn’t hold threads waiting, but any stray
.Resultor.Wait()turns a slow dependency into a thread starvation problem.
Bulkhead on input: rate limiting in ASP.NET Core
So far we have protected calls outward. The same principle works on requests that enter the application. The rate limiting middleware in ASP.NET Core allows isolating costly endpoints so they don’t consume resources of critical ones:
builder.Services.AddRateLimiter(options =>
{
    options.RejectionStatusCode = StatusCodes.Status503ServiceUnavailable;

    options.AddConcurrencyLimiter("rapoarte", limiter =>
    {
        limiter.PermitLimit = 5;
        limiter.QueueLimit = 10;
        limiter.QueueProcessingOrder = QueueProcessingOrder.OldestFirst;
    });
});

app.UseRateLimiter();

app.MapGet("/api/rapoarte/anual", GenerateAnnualReport)
   .RequireRateLimiting("rapoarte");
Maximum 5 annual reports generated simultaneously, regardless of how many users press the button. The rest of the application, including invoice issuance, feels nothing.
Summary
- Retry handles short failures. Circuit breaker handles persistent failures, completely stopping calls to a sick dependency.
- Closed, Open, Half-Open: in Half-Open, a single test call decides if the circuit closes.
- In Polly v8, the breaker is based on failure rate. Tune
FailureRatio,MinimumThroughput,SamplingDuration, andBreakDurationaccording to the real profile of the dependency. - Order: total timeout, retry, circuit breaker, timeout per attempt. Do not retry
BrokenCircuitException. - One breaker per dependency and, where applicable, per host (
SelectPipelineByAuthority). CircuitBreakerManualControlfor announced maintenance windows.- Bulkhead limits simultaneous calls per dependency, so a single problem doesn’t consume everyone’s resources.
- Apply the same principle on input, with ASP.NET Core rate limiting.
Resilience in .NET series
- Fundamentals and Polly v8
- Smart retry policies
- Circuit breaker and bulkhead — this article
- Advanced health checks
- Graceful degradation
- Chaos engineering basics
In the next article, we move from what the application does with its dependencies to how it communicates its own state: /health/live vs. /health/ready, startup probes, and why a database in the liveness probe can turn a minor problem into a cascading restart.